THE PERSONAL DAILYThursday, October 8, 2026Issue 003 / Edited edition
From your following Edited for reading
X PaperREAD
Your following. Your daily paper.
Take time to read See who said what
81 followed sources · This issue 13 storiesNamed voices · Traceable sources
IN THIS ISSUE
Costs, expectations and public life on the front; tools moving from answers to actions on the back.
OCT 08
AI & Technology
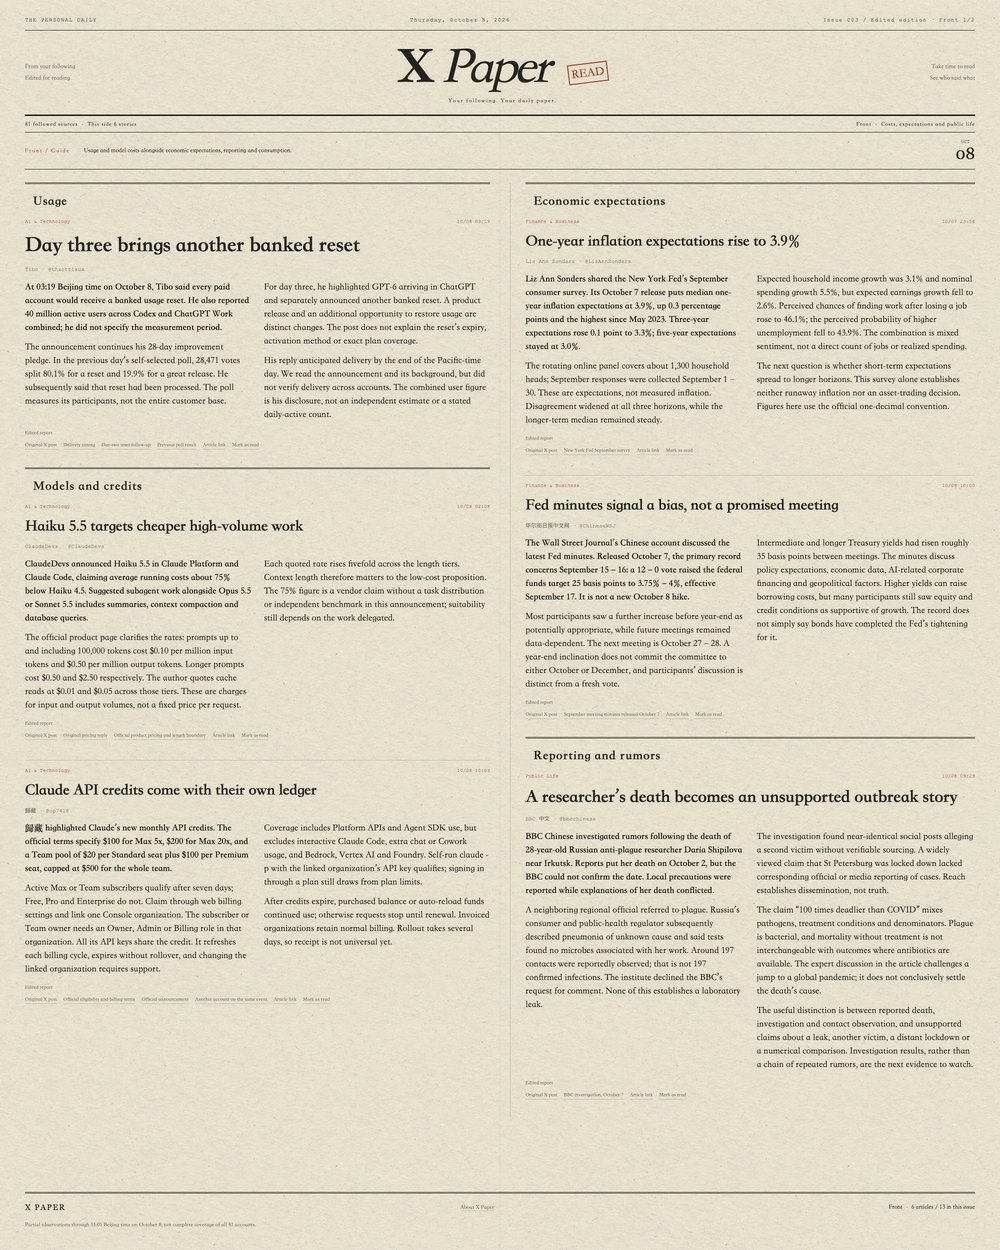
Day three brings another banked reset
Tibo · @thsottiaux
At 03:19 Beijing time on October 8, Tibo said every paid account would receive a banked usage reset. He also reported 40 million active users across Codex and ChatGPT Work combined; he did not specify the measurement period.
The announcement continues his 28-day improvement pledge. In the previous day’s self-selected poll, 28,471 votes split 80.1% for a reset and 19.9% for a great release. He subsequently said that reset had been processed. The poll measures its participants, not the entire customer base.
For day three, he highlighted GPT-6 arriving in ChatGPT and separately announced another banked reset. A product release and an additional opportunity to restore usage are distinct changes. The post does not explain the reset’s expiry, activation method or exact plan coverage.
His reply anticipated delivery by the end of the Pacific-time day. We read the announcement and its background, but did not verify delivery across accounts. The combined user figure is his disclosure, not an independent estimate or a stated daily-active count.
ClaudeDevs announced Haiku 5.5 in Claude Platform and Claude Code, claiming average running costs about 75% below Haiku 4.5. Suggested subagent work alongside Opus 5.5 or Sonnet 5.5 includes summaries, context compaction and database queries.
The official product page clarifies the rates: prompts up to and including 100,000 tokens cost $0.10 per million input tokens and $0.50 per million output tokens. Longer prompts cost $0.50 and $2.50 respectively. The author quotes cache reads at $0.01 and $0.05 across those tiers. These are charges for input and output volumes, not a fixed price per request.
Each quoted rate rises fivefold across the length tiers. Context length therefore matters to the low-cost proposition. The 75% figure is a vendor claim without a task distribution or independent benchmark in this announcement; suitability still depends on the work delegated.
歸藏 highlighted Claude’s new monthly API credits. The official terms specify $100 for Max 5x, $200 for Max 20x, and a Team pool of $20 per Standard seat plus $100 per Premium seat, capped at $500 for the whole team.
Active Max or Team subscribers qualify after seven days; Free, Pro and Enterprise do not. Claim through web billing settings and link one Console organization. The subscriber or Team owner needs an Owner, Admin or Billing role in that organization. All its API keys share the credit. It refreshes each billing cycle, expires without rollover, and changing the linked organization requires support.
Coverage includes Platform APIs and Agent SDK use, but excludes interactive Claude Code, extra chat or Cowork usage, and Bedrock, Vertex AI and Foundry. Self-run claude -p with the linked organization’s API key qualifies; signing in through a plan still draws from plan limits.
After credits expire, purchased balance or auto-reload funds continued use; otherwise requests stop until renewal. Invoiced organizations retain normal billing. Rollout takes several days, so receipt is not universal yet.
Liz Ann Sonders shared the New York Fed’s September consumer survey. Its October 7 release puts median one-year inflation expectations at 3.9%, up 0.3 percentage points and the highest since May 2023. Three-year expectations rose 0.1 point to 3.3%; five-year expectations stayed at 3.0%.
The rotating online panel covers about 1,300 household heads; September responses were collected September 1–30. These are expectations, not measured inflation. Disagreement widened at all three horizons, while the longer-term median remained steady.
Expected household income growth was 3.1% and nominal spending growth 5.5%, but expected earnings growth fell to 2.6%. Perceived chances of finding work after losing a job rose to 46.1%; the perceived probability of higher unemployment fell to 43.9%. The combination is mixed sentiment, not a direct count of jobs or realized spending.
The next question is whether short-term expectations spread to longer horizons. This survey alone establishes neither runaway inflation nor an asset-trading decision. Figures here use the official one-decimal convention.
The Wall Street Journal’s Chinese account discussed the latest Fed minutes. Released October 7, the primary record concerns September 15–16: a 12–0 vote raised the federal funds target 25 basis points to 3.75%–4%, effective September 17. It is not a new October 8 hike.
Most participants saw a further increase before year-end as potentially appropriate, while future meetings remained data-dependent. The next meeting is October 27–28. A year-end inclination does not commit the committee to either October or December, and participants’ discussion is distinct from a fresh vote.
Intermediate and longer Treasury yields had risen roughly 35 basis points between meetings. The minutes discuss policy expectations, economic data, AI-related corporate financing and geopolitical factors. Higher yields can raise borrowing costs, but many participants still saw equity and credit conditions as supportive of growth. The record does not simply say bonds have completed the Fed’s tightening for it.
A researcher’s death becomes an unsupported outbreak story
BBC 中文 · @bbcchinese
BBC Chinese investigated rumors following the death of 28-year-old Russian anti-plague researcher Daria Shipilova near Irkutsk. Reports put her death on October 2, but the BBC could not confirm the date. Local precautions were reported while explanations of her death conflicted.
A neighboring regional official referred to plague. Russia’s consumer and public-health regulator subsequently described pneumonia of unknown cause and said tests found no microbes associated with her work. Around 197 contacts were reportedly observed; that is not 197 confirmed infections. The institute declined the BBC’s request for comment. None of this establishes a laboratory leak.
The investigation found near-identical social posts alleging a second victim without verifiable sourcing. A widely viewed claim that St Petersburg was locked down lacked corresponding official or media reporting of cases. Reach establishes dissemination, not truth.
The claim “100 times deadlier than COVID” mixes pathogens, treatment conditions and denominators. Plague is bacterial, and mortality without treatment is not interchangeable with outcomes where antibiotics are available. The expert discussion in the article challenges a jump to a global pandemic; it does not conclusively settle the death’s cause.
The useful distinction is between reported death, investigation and contact observation, and unsupported claims about a leak, another victim, a distant lockdown or a numerical comparison. Investigation results, rather than a chain of repeated rumors, are the next evidence to watch.
交易员 shared falling National Day box office and admissions figures. Beijing Daily, citing Dengta at 20:14 on October 7, reported RMB 1.156 billion and 31.76 million admissions. CCTV’s platform-based closing figure was RMB 1.164 billion. These timestamps should not be silently combined.
The China Film Administration’s published 2025 totals were RMB 1.835 billion and 50.07 million admissions. The followed post calculates declines using more precise 2026 numbers, but we did not obtain the matching 2026 official release and do not label that precision officially verified.
The available reports support a closing total near RMB 1.16 billion. Explaining the decline requires aligned cutoff times, holiday lengths, screenings and films. Gross revenue alone cannot distinguish changing attendance, ticket prices or audience preferences.
Gorden Sun introduced Liquid AI’s d1 family. The d1-3B model card describes a single forward pass over text, JSON or image state plus specified questions, returning typed decisions and confidence information rather than autoregressive chat text.
The public model has about 3.12 billion parameters and a 32,768-token context. Routing, triage, classification, reranking and visual inspection are proposed uses. Zero generated output tokens describes its computation, not free execution.
The card reports median warm single-question latency of 8 ms on an RTX 4090 and 50 ms on a Jetson Orin Nano under specified precision, compilation and warm-up conditions. A longer 3.4K-token state takes 102 ms and 1,640 ms respectively. The headline latency is not a guarantee for arbitrary input.
These are publisher measurements, not our hardware tests. Weights use LFM Open License 1.0; availability does not establish unrestricted open-source licensing. Another model in the family has separate capabilities.
SDK toolsets simplify wiring, not the whole browser
ClaudeDevs · @ClaudeDevs
ClaudeDevs announced toolsets in the Python and TypeScript SDKs to run tool loops and route actions such as clicks and typing to a driver. The official beta browser documentation shows which work remains with the developer.
The abstract toolset needs a supplied browser or desktop, implemented navigation and click methods, and returned state. The SDK handles registration, dispatch, results and policy configuration. The quickstart is a sample, not a complete production browser or ready-made driver.
Address restrictions and confirmation rules still need configuration. A navigation URL policy does not automatically govern every page request. Purchases or messages can appear as ordinary clicks at the tool layer. Execution plumbing and meaningful access boundaries remain separate responsibilities.
Many iterations may start with missing domain knowledge
Thariq · @trq212
Thariq described a recurring failure: people working outside their expertise cannot make prompts and plans precise, so they spend many turns iterating imprecisely. His focus is task definition, not only the price of each model call.
The post responds to a personal chess-app anecdote claiming heavy token use. We did not independently verify that case or generalize its costs. In a reply, he suggests asking an agent to teach unfamiliar domain concepts before trying to specify the work.
This is a practitioner’s observation, not a controlled study. It raises useful questions about whether a task can be clearly accepted and whether its requester can judge the result. It does not establish that users cause every agent failure.
GrokBot announces X monitoring; persistence is untested
Gorden Sun · @Gorden_Sun
Gorden Sun shared GrokBot’s announced ability to search, read and monitor X. The linked bot announcement confirms those three actions but gives no monitoring frequency, quota, access scope or durable export mechanism.
歸藏 suggested notifications when Tibo posts a reset as an example. We have not tested reliable new-post detection, edits, retries or delivery into an editorial pipeline. A no-traditional-API proposition does not yet establish a dependable free media collector.
Starlink Mobile announces a Bangladesh partnership
Elon Musk · @elonmusk
Elon Musk relayed Starlink’s announcement of a Starlink Mobile partnership with Bangladesh’s Banglalink, describing app connectivity, messaging and location for compatible phones beyond cellular coverage.
The proposition is filling terrestrial coverage gaps. We read the announcement but did not obtain complete plans, handset lists, speeds or activation terms, or test service. It does not establish unlimited high-speed access or voice on every phone nationwide.
Tibo relayed OpenAI’s announcement of GPT-6 and an intelligent interface for ChatGPT users, emphasizing interactive visual answers and tools for understanding questions or completing tasks.
This is distinct from the same-day usage reset: an interface changes presentation and interaction, while a reset changes available usage. The post does not give full device, regional or plan rollout terms. We did not test accounts, so the announced broad rollout is not proof of immediate access everywhere or universal task improvement.